avatar
Siz Long

My name is Siz. I am a computer science graduate student specializing in backend development with Golang and Python, seeking opportunities in innovative tech projects. My personal website is longsizhuo.com .Connect with me on LinkedIn: https://www.linkedin.com/in/longsizhuo/.

  • Resume
  • Archives
  • Categories
  • Photos
  • Music


{{ date }}

{{ time }}

avatar
Siz Long

My name is Siz. I am a computer science graduate student specializing in backend development with Golang and Python, seeking opportunities in innovative tech projects. My personal website is longsizhuo.com .Connect with me on LinkedIn: https://www.linkedin.com/in/longsizhuo/.

  • 主页
  • Resume
  • Archives
  • Categories
  • Photos
  • Music

9021_TUT_5

  2024-10-08
字数统计: 2.6k字   |   阅读时长: 16min

Exercise 1

Problem Description

We are given a list L and an integer n. The task is to repeatedly extend the list L a certain number of times (n) by multiplying each element of the list by an increasing factor. The factors start at 2 and increase by 1 for each iteration.


In my solution, I used a while loop to iterate n times. In each iteration, I used a list comprehension to multiply each element of the list L by the current factor and then used the extend() method to add the new elements to the end of the list. Finally, I incremented the factor by 1 and decremented n by 1.
Because of the description: L'' == 3 * L', L' == 2 * L ….

My Solution

1
2
3
4
5
6
7
8
9
10
11
def f1(L: list, n: int):
# because of the des of L'' == 3 * L', L' == 2 * L ....
base = 2
# when n bigger than 0, base will always ++,
while n:
# I want use map() again, but list generator is more simple
# extend() will add all the elements in the list to the end of the list
L.extend([i * base for i in L])
base += 1
n -= 1
return L

Standard Solution

1
2
3
4
def f1(L, n):
for i in range(2, n + 2):
L.extend([e * i for e in L])
return L

Explanation

  1. My Solution: Uses a while loop where n is manually decremented after each iteration step by step since it can help me understand what we need. I keep track of the current base manually (base += 1).
  2. Standard Solution: Uses a for loop, which automatically increments i in each iteration. The range is explicitly set to go from 2 to n + 2, which avoids the need for manually handling the base.

Exercise 2

Problem Description

We are given a list L and an integer n. The task is to extend the list L such that it becomes the first n members of an infinite list, which is defined as:

  • L, followed by 2 * L, followed by 4 * L, followed by 8 * L, and so on.

This means that:

  • L is initially concatenated with 2 * L (all elements of L multiplied by 2).
  • Then, 4 * L (all elements of L multiplied by 4) is concatenated, followed by 8 * L, and so on, until the length of the list is at least n.

The challenge is to achieve this without using any for or while loops.


We can see the pattern here: L, 2 * L, 4 * L, 8 * L, ... until it reaches the length of n.

At first, I ignored the description that “without using any for or while loops.”

Here is my solution:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
# Assume that the argument L is a nonempty list of integers
# and the argument n is an integer at least equal to the
# length of L.
#
# Given an integer x and a list of integers S,
# let x * S denote the list obtained from S
# by multiplying all its elements by x.
#
# L becomes the first n members of the infinite list
# defined as L concatenated with 2 * L concatenated
# with 4 * L concatenated with 8 * L...
#
# Use no for nor while statement.
def f2(L: list, n: int):
while len(L) < n:
L.extend([i * 2 for i in L])
# use the slice to cut the list to reach the length of n
return L[:n]

Standard Solution

1
2
3
def f2(L, n):
L.extend(e * 2 for e in L if len(L) < n)
return L

Exercise 3

Problem Description

The goal of this problem is to process a list L, which contains nonempty lists of nonempty lists of integers, and return a pair of lists. Each of these lists will be filtered based on specific conditions related to the length of the sublists and the values inside them.

Here’s the task broken down:

  1. First List in the Pair:

    • For each sublist L' of L, if the length of L' is at least n, then:
    • For each sublist L'' of L', if the sum of the elements of L'' is strictly positive:
    • Collect all the strictly positive integers from L'' and add them to the first list.
  2. Second List in the Pair:

    • This is similar to the first list but slightly simpler:
    • For each sublist L' of L, if its length is at least n:
    • For each sublist L'' of L', if the sum of its members is strictly positive:
    • Directly collect all the strictly positive integers from L'' and add them to the second list.

The task specifies that we must use list comprehensions only—no loops, functions, or other control structures.

My Solution

1
2
3
4
5
6
7
8
9
10
11
12
13
def f3(L, n):
# First list comprehension: we process L' for length and filter based on sum
first = [
[x for L2 in L1 if sum(L2) > 0 for x in L2 if x > 0]
for L1 in L if len(L1) >= n
]

# Second list comprehension: similar filtering but simpler output structure
second = [
[x for x in L2 if x > 0]
for L1 in L if len(L1) >= n for L2 in L1 if sum(L2) > 0
]
return first, second

Explanation

  1. First List (first):

    • We first filter out the sublists L1 whose length is at least n (for L1 in L if len(L1) >= n).
    • Inside this, for each valid L1, we process its members L2 (which are sublists of integers). We check if the sum of elements of L2 is strictly positive (if sum(L2) > 0).
    • For each valid L2, we collect the strictly positive integers (for x in L2 if x > 0).
    • This gives us the first list of lists, where each list contains the positive integers from sublists of sublists whose sum is positive.
  2. Second List (second):

    • Similar to the first list, but here we directly collect the strictly positive integers from the valid sublists L2, without additional nesting.
    • We again check that the sum of L2 is strictly positive and that the length of L1 is at least n.
    • The result is a more flattened structure than the first list.
  3. Key Concepts:

    • Filtering: Both lists involve filtering based on the length of L1 and the sum of L2.
    • List Comprehensions: Used extensively to meet the problem’s requirement of not using explicit loops or other control structures.

Standard Solution

1
2
3
4
5
6
7
8
9
10
def f3(L, n):
return ([[e for L2 in L1 if sum(L2) > 0
for e in L2 if e > 0
] for L1 in L if len(L1) >= n
],
[[e for e in L2 if e > 0]
for L1 in L if len(L1) >= n
for L2 in L1 if sum(L2) > 0
]
)

Exercise 4

We are given a list L of integers, and the goal is to return a list of lists that consists of pairs of elements from the beginning and end of the list. Specifically:

  1. The number of pairs n at the beginning and the end should be as large as possible while maintaining symmetry.
  2. If the length of L is odd, the remaining element in the middle (that cannot form a pair) should be included as a single list.
  3. No for or while loops should be used in the implementation.

My Solution

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
def f4(L: list[int]) -> list[list[int]]:
# Calculate the number of pairs we can take from both the beginning and end.
n = len(L) // 2

# Take pairs from the beginning of the list. These are the first n // 2 pairs.
start_pairs = [L[i:i + 2] for i in range(0, len(L) // 4 * 2, 2)]

# Take pairs from the end of the list. These are the last n // 2 pairs.
end_pairs = [L[i:i + 2] for i in range(len(L) - (len(L) // 4 * 2), len(L) - 1, 2)]

# Calculate the remaining part (middle element if the list length is odd).
remain_part = [L[len(L) // 4 * 2 : len(L) -(len(L) // 4 * 2)]] if len(L) % 4 else []

# Combine the start pairs, the remaining part (if any), and the end pairs.
return start_pairs + remain_part + end_pairs if remain_part else start_pairs + end_pairs

Standard Solution

1
2
3
4
5
6
def f4(L):
if len(L) % 2:
return [L[i : i + 2] for i in range(0, len(L) // 4 * 2, 2)] +\
[L[len(L) // 4 * 2 : len(L) -(len(L) // 4 * 2)]] +\
[L[i : i + 2] for i in range(len(L) - (len(L) // 4 * 2), len(L) - 1, 2)]
return [L[i : i + 2] for i in range(0, len(L) - 1, 2)]

Explanation

The reason of why we use len(L) // 4 * 2 is that we want to get the number of pairs we can take from both the beginning and end.

We have a pair at the beginning and a pair at the end, so we need to divide the length of the list by 4 to get the number of pairs. We then multiply this by 2 to get the total number of elements in these pairs.

Exercise 5

Before E5, let’s do some exercises.

Normal dictionary:

1
2
3
4
5
6
7
8
9
d = {}
for i in ['a','b','c','a','b','c']:
if i in d:
d[i] += 1
else:
# need to initialize the value of the key
d[i] = 1

print(d)

defaultdict:

1
2
3
4
5
6
7
8
from collections import defaultdict

d = defaultdict(int)
for i in ['a','b','c','a','b','c']:
# no need to initialize the value of the key
d[i] += 1

print(d)

Counter:

1
2
3
4
5
6
from collections import Counter

# easy to count the number of each element
d = Counter(['a','b','c','a','b','c'])

print(d)

Problem Description

The task is to count the number of customers from different countries by reading a CSV file and then printing the count per country in alphabetical order.

The provided solutions use Python’s csv module to read the data and a dictionary (from the collections.defaultdict class) to keep track of the count of customers from each country.

My Solution

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
import csv
from collections import defaultdict

def f5(filename= 'customers-100.csv') -> None:
# read the file
with open(filename, newline='') as csvfile:
reader = csv.reader(csvfile)
next(reader) # skip the header

# count the number of customers per country
count = defaultdict(int)
for row in reader:
count[row[6]] += 1 # country is in the 7th column

# Print the results sorted by country name
for key, value in sorted(count.items()):
print(f'{value} from {key}')

Standard Solution

1
2
3
4
5
6
7
8
9
10
11
12
13
import csv
from collections import defaultdict

countries = defaultdict(int)
with open('customers-100.csv') as file:
_ = next(file) # skip the header
csv_file = csv.reader(file)
for records in csv_file:
countries[records[6]] += 1 # country data is in the 7th column

# Print the results sorted by country name
for country in sorted(countries):
print(countries[country], 'from', country)

Additional Solution

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
import csv
from collections import Counter

def f5_counter(filename='customers-100.csv') -> None:
with open(filename, newline='') as csvfile:
reader = csv.reader(csvfile)
next(reader) # skip the header

# Create a Counter from the country column (assumed to be the 7th column)
country_counter = Counter(row[6] for row in reader)

# Print the results sorted by country name
for key, value in sorted(country_counter.items()):
print(f'{value} from {key}')

f5_counter()

Additional Additional Solution (Data Analysis) (NOT Mandatory)

Not Mandatory, but it’s a good way to learn how to use pandas to do data analysis.

1
2
3
4
5
6
7
8
9
10
import pandas as pd

# read file by pandas
df = pd.read_csv("customers-100.csv")

# use pandas' count()
country_counts = df['Country'].value_counts().sort_index()

for country, count in country_counts.items():
print(f'{count} from {country}')

Explanation

Reading the CSV file:

1
df = pd.read_csv(filename)

Using the read_csv() function, Pandas can directly load a CSV file into a DataFrame object, which is similar to a table structure. Each column becomes an attribute of the DataFrame, and the column names automatically become the labels for the DataFrame.

Counting the number of customers per country:

1
df['Country'].value_counts()

Pandas provides the value_counts() method, which can directly count the frequency of each value in a column. Here, we call value_counts() on the Country column to get the number of customers from each country.

Exercise 6

Problem Description

The task is to create a directory structure where:
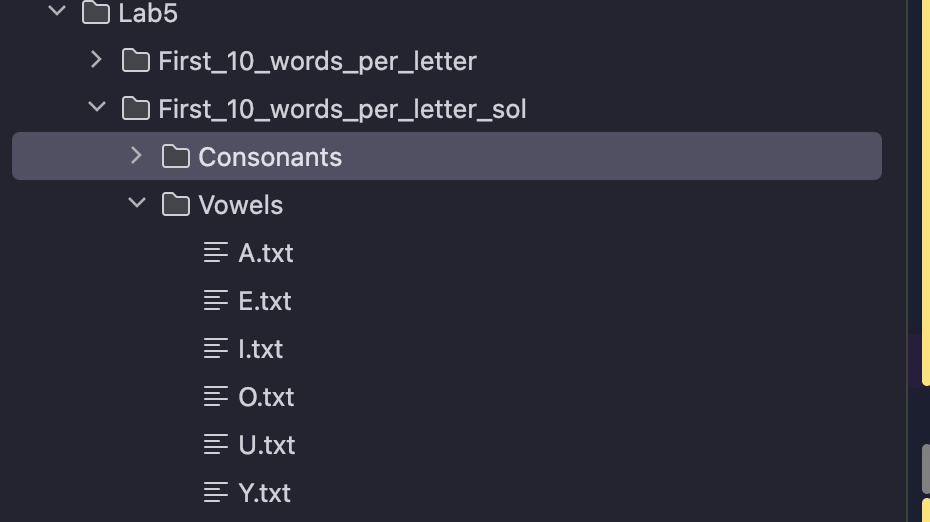
2024-10-08.png

  • There is a top-level directory named First_10_words_per_letter.
  • Under this directory, there are two subdirectories:
    • Vowels: Containing files for letters A, E, I, O, U, Y.
    • Consonants: Containing files for the rest of the letters in the alphabet (B, C, D, etc.).
  • Each letter (A to Z) has its own file, and each file contains the first 10 words from a dictionary.txt file that start with that letter.
  • The directory structure and the files should be generated programmatically, without using any existing hierarchy.

My Solution(Not Perfect, it relies on the sort of dictionary.txt )

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31

import os
from pathlib import Path
from string import ascii_uppercase

def main():
# Create the top directory
top_dir = Path('First_10_words_per_letter')
# Create the subdirectories
vowels_dir = top_dir / 'Vowels'
consonants_dir = top_dir / 'Consonants'
os.makedirs(vowels_dir)
os.makedirs(consonants_dir)

# Create the files for each letter
with open('dictionary.txt') as f:
for letter in ascii_uppercase:
# Read the first 10 words starting with the letter
count = 0
# Write the words to the file
letter_dir = vowels_dir if letter in 'AEIOUY' else consonants_dir
with open(letter_dir / f'{letter}.txt', 'w') as f2:
for word in f:
if word[0] == letter:
f2.write(word)
count += 1
if count >= 10:
break

if __name__ == '__main__':
main()

Explanation

Explanation of My Solution:

  1. Creating Directories:

    • I use os.makedirs() to create the top directory (First_10_words_per_letter) and its subdirectories (Vowels and Consonants).
  2. Reading the Dictionary File:

    • The program reads from dictionary.txt and processes each letter in the alphabet (ascii_uppercase).
    • For each letter, I decide whether to place the corresponding file in the Vowels or Consonants subdirectory based on whether the letter is a vowel or consonant.
  3. Writing the Words:

    • The program writes the first 10 words starting with the given letter into the corresponding .txt file.
  4. Potential Issue:

    • here is some limitations of this. Say that processing the dictionary on the fly would not be an option if the words in the file were not lexicographically ordered?
      [//]: # ( - One small mistake is that the file handle f for the dictionary.txt file is shared across iterations, but the file is being processed linearly. Once a word is read, it is not reset for the next letter. This will cause issues because the loop keeps reading until the end of the file and will skip words that should be in earlier letters.)

Standard Solution

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
import os
from pathlib import Path
from string import ascii_uppercase

top_dir = Path('First_10_words_per_letter')
os.mkdir(top_dir)
vowels_dir = top_dir / 'Vowels'
consonants_dir = top_dir / 'Consonants'
os.mkdir(vowels_dir)
os.mkdir(consonants_dir)

with open('dictionary.txt') as dictionary:
for letter in ascii_uppercase:
letter_dir = vowels_dir if letter in 'AEIOUY' else consonants_dir
count = 0
with open(letter_dir / f'{letter}.txt', 'w') as filename:
for word in dictionary:
if word[0] != letter:
continue
if count >= 10:
break
print(word, file=filename, end='')
count += 1
  • Python
  • 9021
  • TUT

show all >>

9021_TUT_4

  2024-10-01
字数统计: 2.4k字   |   阅读时长: 14min

Exercise 1

Problem Description

At first, I thought this exercise was about dividing by a modulus, where the modulus would always be incremented by one. But then I realized that in some cases, there’s no “2” in the division sequence. For example, for 12, the answer is 12 6 3 1\n. This indicates that the number is always being divided by 2.

When we look at the examples of these answers, we can see that the format aligns each number to the right, based on the width of the largest number.

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
%%run_and_test python3 -c "from exercise_4_1 import f1; f1(13)"

'''
13 6 3 1\n
12 6 3 1\n
11 5 2 1\n
10 5 2 1\n
9 4 2 1\n
8 4 2 1\n
7 3 1\n
6 3 1\n
5 2 1\n
4 2 1\n
3 1\n
2 1\n
1\n
'''

So we have the following solution:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
# Assume that the argument n is an integer at least equal to 1.
#
# Each integer is printed out in a field of size equal to
# the number of digits in n plus 1.
#
# The output is printed out, not returned.

def f1(n):
w = len(str(n)) + 1
for i in range(n, 0, -1):
while i:
print(f'{i:{w}}', end="")
i = i // 2
print()
return

Complexity Analysis

The time complexity of this algorithm is O(n log n), where n is the input number. This is because we are dividing the number by 2 until we reach 1. The space complexity is O(1) because we are not using any additional data structures.

Exercise 2

Problem Description

This exercise asks us to repeatedly remove the maximum number from the set until only one element remains. The line print(“A list of sets:”, all(isinstance(x, set) for x in S)) checks if the return value of f2 is a list of sets.

In my solution:

1
2
3
4
5
6
7
8
def f2(S: set[int]):
ans = []
s_list = list(S) # Convert the set to a list
s_list.sort() # Sort the list
while len(s_list) > 0:
ans.append(set(s_list)) # Append the current set
s_list.pop() # Pop the last (largest) element
return ans

I convert the set to a list because tuples don’t have a sort() method. So I convert it, sort it, and then pop the largest element (which is at the end of the list) while the length is greater than 1.

The standard solution is:

1
2
3
4
5
6
def f2(S):
U = [set(S)]
while len(S) > 1:
S.remove(max(S)) # Remove the maximum element
U.append(set(S)) # Append the current set
return U

The standard solution is simpler; it uses max() to find and remove the largest element, then appends the result to the list.

Standard solution is better because it is more concise and uses less memory.

Exercise 3

Problem Description

As per the description of Exercise 4, we need to remove elements that are equal to the mean value of their neighboring elements (i.e., the element is the average of the one just before and the one just after it).
Please pay attention to the special challenge: use only one loop without any break or continue statements, and only one if statement (with no elif nor else statements).

In my solution:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
# Assume that the argument L is an increasing list of integers.
#
# Keep removing any member of the list
# that is neither the first one nor the last one
# and that is the average of the one just before and the one just after.
#
# Special challenge: use only one loop without any break or continue statements,
# and only one if statement (with no elif nor else statements).
def f3(L):
for i in range(len(L) - 2):
if L[i] + L[i + 2] == 2 * L[i + 1]: # Check if the middle element is the average
L.pop(i + 1) # Remove the element if it satisfies the condition
return f3(L) # Recurse to check the rest of the list
return L

Explanation:

  • The function iterates through the list, checking if any element (except the first and last) is the average of its neighbors.

  • If an element meets this condition, it’s removed using pop(), and the function calls itself recursively to continue checking the remaining list.

  • This approach ensures that all elements satisfying the condition are removed.

  • The main reason for using recursion in the original code is to avoid i going beyond the scope of the list, because the length of the list changes each time an element is deleted, so in the original for loop, the index may exceed the length of the list. Recursion avoids this situation by re-calling the function and re-traversing the list from the beginning.

When we use for i in sth. in Python, i is essentially a “view” or a “shallow copy” of the elements in sth.. Modifying i directly will not change sth. itself. Additionally, we cannot modify the value of i, because in each iteration of the loop, i is reset to the next element in the sequence.
This means that if we use a for loop directly in this context, and we remove an element from the list during the loop, the list will get shorter. As a result, i could end up being out of range in subsequent iterations of the loop.

The standard solution is:

1
2
3
4
5
6
7
def f3(L):
i = 0
while (i := i + 1) < len(L) - 1:
if L[i - 1] + L[i + 1] == L[i] * 2:
L.pop(i)
i -= 1
return L

Explanation:

The while loop version of the code does avoid recursion, and manually manages the value of i to ensure that the index does not exceed the range after the list is deleted. This reduces the complexity of the recursive call while achieving the same effect.

Key points:

  • The function uses only one loop and one if statement as required by the challenge.
  • Recursion is used to continue processing after each removal.

Exercise 4

Problem Description

You are given an integer n, and the goal is to express n as a sum (or difference) of powers of 2. This should be done by leveraging the binary representation of n.
Specifically, you need to:

  1. Convert n to its binary form.
  2. Identify which positions in the binary form have a 1.
  3. Use these positions to generate the corresponding powers of 2.
  4. If n is positive, add the powers of 2 together. If n is negative, subtract the powers of 2.
    The output should be in the form of an equation, displaying the original number as the sum (or difference) of powers of 2.

Example 1:

For n = 13:

The binary representation of 13 is 1101.
This corresponds to 2^3 + 2^2 + 2^0, because the 3rd, 2nd, and 0th positions in the binary number are 1.

Output: 13 = 2^3 + 2^2 + 2^0

Explanation:

The function f4(n) converts an integer n into a sum of powers of 2 based on its binary representation. Let’s go through the code:

  1. Handling the case when n is zero:

    1
    2
    3
    if not n:
    print('0 = 0')
    return

    This part checks if n is zero using if not n. If n is zero, the function prints 0 = 0 and returns immediately, since zero doesn’t need further decomposition into powers of 2.

  2. Converting the number to binary:

    1
    binary_n = f'{n:b}'

    The f'{n:b}' converts the integer n to its binary form as a string (without the 0b prefix). For example, if n = 13, binary_n will be 1101.

  3. Finding the positions of 1s in the binary representation:

    1
    powers = (i for i in range(len(binary_n)) if binary_n[i] == '1')

    This list comprehension creates a list of indices where the binary digit is 1. For 1101, the positions list will be [0, 2, 3].

    • This is a generator expression that finds the positions (indices) in the binary string where there is a 1.
    • range(len(binary_n)) iterates over each character in the binary string, and the condition binary_n[i] == '1'filters out the positions where there is a 1.
    • For example, if n = 13 and binary_n = '1101', the positions of 1s would be (0, 2, 3), because the first, third, and fourth bits from the right are 1.
  4. print(operator.join(f’2^{len(binary_n) - i - 1}’ for i in powers))

    1
    print(operator.join(f'2^{len(binary_n) - i - 1}' for i in powers))
    • This is the key part of the function that prints the powers of 2 based on the positions of 1s in the binary representation.
      • f'2^{len(binary_n) - i - 1}' creates strings like 2^3, 2^2, 2^0 by converting each position i into the corresponding exponent for 2. The exponent is calculated as len(binary_n) - i - 1, where i is the position of the 1 in the binary string.
      • operator.join(...) joins all these terms together with either' + 'or' - 'depending on the value of n.

Exercise 5

To solve next problems, lets first understand the zip function in Python.

  1. Let’s try:
1
2
3
L1 = [1, 2, 3]
L2 = [4, 5, 6]
print(list(zip(L1, L2)))

Output:

1
[(1, 4), (2, 5), (3, 6)]

And zip in dictionary:

1
2
3
L1 = [1, 2, 3]
L2 = [4, 5, 6]
print(dict(zip(L1, L2)))

Output:

1
2
[(1, 4), (2, 5), (3, 6)]
{1: 4, 2: 5, 3: 6}

The finally we try using zip with *, which is used to unpack the elements of a list or tuple:

1
2
3
4
5
6
L = [[1, 2, 3], [4, 5, 6], [7, 8, 9]]
for i in zip(L):
print(i)

for i in zip(*L):
print(i)

Output:

1
2
3
4
5
6
([1, 2, 3],)
([4, 5, 6],)
([7, 8, 9],)
(1, 4, 7)
(2, 5, 8)
(3, 6, 9)

Problem Description

In this problem, we can identify the pattern by observing the example: start from the first and last elements of a list and progressively make pairs towards the center of the list.

My initial thought was to use a two-pointer approach: one pointer starts at the beginning of the list, and the other starts at the end, and they move towards each other. However, I missed the specific requirement in the problem: “Return an expression built only from list, reversed, and zip.”

Wrong Solution:

1
2
3
4
5
6
7
8
9
def f5(*L):
ans = []
left = 0
right = len(L) - 1
while left < len(L):
ans.append(((L[left], L[right]), (L[right], L[left])))
left += 1
right -= 1
return ans

Correct Solution:

1
2
def f5(*L):
return list(zip(zip(L, reversed(L)), reversed(list(zip(L, reversed(L))))))

The idea behind the correct solution is as follows:

  1. zip(L, reversed(L)) creates pairs of elements where the first comes from L and the second comes from reversed(L) (i.e., L reversed).
    Example: If L = (1, 2, 3), then reversed(L) is (3, 2, 1). So, zip(L, reversed(L)) results in [(1, 3), (2, 2), (3, 1)].

  2. reversed(list(zip(L, reversed(L)))): Here, we convert the result of zip(L, reversed(L)) into a list and then reverse the entire list.
    Example: If zip(L, reversed(L)) produced [(1, 3), (2, 2), (3, 1)], then reversed(list(zip(L, reversed(L)))) will return [(3, 1), (2, 2), (1, 3)].

  3. zip(zip(L, reversed(L)), reversed(list(zip(L, reversed(L))))): This part pairs the result of zip(L, reversed(L)) with its reversed version. It takes corresponding elements from both sequences and forms pairs.
    Example: If zip(L, reversed(L)) is [(1, 3), (2, 2), (3, 1)] and its reverse is [(3, 1), (2, 2), (1, 3)], then zip(zip(L, reversed(L)), reversed(list(zip(L, reversed(L))))) produces pairs of tuples like:

    • ((1, 3), (3, 1))
    • ((2, 2), (2, 2))
    • ((3, 1), (1, 3))

Finally, this expression is wrapped in list() to convert the zip object into a list of tuples.

Exercise 6

Problem Description

Exercise 6 is similar to Exercise 5, requiring us to use zip, *, and list to solve the problem. We are given a variable number of arguments *L, and the goal is to output them in the form of [(...), (...)]. This task is simpler than the previous one, as the pairing only needs to reverse and mirror the elements.

At first, I attempted the following approach:

Wrong Solution:

1
2
def f6(*L):
return list(zip(zip(L, reversed(L)), zip(reversed(L), L)))

I tried using zip to pair elements in forward and reverse order:

zip(L, reversed(L)) pairs the elements of L with the reversed version of L, while zip(reversed(L), L) pairs them in the reverse order.

However, the output of this solution was:

[((0, 1), (1, 0)), ((1, 0), (0, 1))]

This did not meet the requirements, as the pairs (0, 1) and (1, 0) were grouped separately. The correct format should have 0, 1, 1, 0 in the same tuple.

Correct Solution:

1
2
def f6(*L):
return list(zip(*zip(L, reversed(L)), *zip(reversed(L), L)))

Explanation of the Fix:

To achieve the desired output, we need to flatten or “unpack” the pairs created by zip(L, reversed(L)) and zip(reversed(L), L) into individual elements and combine them correctly. This is where the * operator comes in, which unpacks the results from the zip function.

By using * before zip(L, reversed(L)) and zip(reversed(L), L), you effectively unpack the tuples into separate elements, allowing the outer zip function to combine them in the desired form.

  • *zip(L, reversed(L)): This unpacks the paired tuples from L and reversed(L). Instead of getting pairs like (0, 1), it unpacks them into 0, 1, 1, 0.

  • *zip(reversed(L), L): Similarly, this unpacks the reversed pairs.

The final zip call then combines these unpacked elements into the correct tuple format. The result is:

[(0, 1, 1, 0), (1, 0, 0, 1)]

This ensures that the mirrored pairs are placed together in the same tuple as required by the problem.

  • Python
  • 9021
  • TUT

show all >>

DartsInter-Uni Programming Contest Tasks Leaderboard Contest

  2024-09-21
字数统计: 1.6k字   |   阅读时长: 9min

Description:

Darts
https://interunia.unswcpmsoc.com/task/Darts/

Thinking:

This contest is harder than I imaged, this is the second task, and I spent a lot of time but when I checked the Leaderboard and no one has solved it yet, I feel a little bit better.
At first, I thought of simply judging whether this point is in the middle of this circle, using Euclidean distance calculation. But later I found that when there are n circles and m darts, the amount of data is surprisingly large. After the brute force cracking timed out, I had to consider a new method.

We can use the gridded Spatial Indexing, the specific steps are as follows:

1. Spatial division: Divide the entire plane into grids of equal size (Grid), and map the target and dart to the corresponding grid.

Purpose:

  • Reduce the number of targets that need to be calculated.
  • For each dart, you only need to check the targets in its grid and adjacent grids.

2. Map Targets to Grids:

  • Calculate the bounding box of each target.
    • Lower-left corner: ( (x_i - r_i, y_i - r_i) )
    • Upper-right corner: ( (x_i + r_i, y_i + r_i) )
  • Record all grid cells covered by this rectangle and add the target index to these grid cells.

3. Map Darts to Grids:

For each dart, calculate the grid coordinates where it is located.

4. Check if the Dart Hits a Target:

  • For each dart, check all targets in its grid and the adjacent 8 grids.
  • Calculate the distance from the dart to the center of each target and determine whether it is less than or equal to the square of the target’s radius, i.e., ( (dx - x_i)^2 + (dy - y_i)^2 \leq r_i^2 ).

Grid Division Parameters

Grid size (GRID_SIZE):

  • Choose an appropriate grid size, such as 500.
  • The choice of grid size requires a trade-off between space and time efficiency.
1
2
3
4
5
auto get_grid_cell = [&](long long x_n, long long y_n) {
int gx = int((x_n - min_x) / s);
int gy = int((y_n - min_y) / s);
return make_pair(gx, gy);
};

Coordinate mapping function:

Maps actual coordinates to grid coordinates.

  • s is the actual length of each grid cell.
  • $min_x$ and $min_y$ are the minimum values among all target and dart coordinates, used to shift the coordinates.

Mapping Targets to Grids

  • Iterate over all targets and calculate their covered grid ranges.
  • In these grids, record the indices of the targets.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
for (int idx = 0; idx < n; ++idx) {
int x, y, r;
tie(x, y, r) = circles[idx];
long long x_min = x - r;
long long x_max = x + r;
long long y_min = y - r;
long long y_max = y + r;
auto [gx_min, gy_min] = get_grid_cell(x_min, y_min);
auto [gx_max, gy_max] = get_grid_cell(x_max, y_max);
for (int gx = gx_min; gx <= gx_max; ++gx) {
for (int gy = gy_min; gy <= gy_max; ++gy) {
long long key = get_grid_key(gx, gy);
grid[key].push_back(idx); // 存储靶子索引
}
}
}

Mapping Darts to Grids

  • For each dart, calculate the grid cell it belongs to.
  • No need to store darts in grids; we process them directly.

Checking if Darts Hit Targets

  • For each dart, get its grid coordinates ( (gx, gy) ).
  • Check the dart’s grid cell and its 8 adjacent grid cells.
  • For each target in these grids, calculate the distance to the dart.
  • If the distance squared is less than or equal to the target’s radius squared, increment the counter.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
for (const auto& p : points) {
int dx = p.first;
int dy = p.second;
auto [gx, gy] = get_grid_cell(dx, dy);
bool found = false;

// Check the grid and the 8 adjacent grids
for (int ix = gx - 1; ix <= gx + 1; ++ix) {
for (int iy = gy - 1; iy <= gy + 1; ++iy) {
long long key = get_grid_key(ix, iy);
if (grid.count(key)) {
const auto& circle_indices = grid[key];
for (int idx : circle_indices) {
int x, y, r;
tie(x, y, r) = circles[idx];
// caculate the distance
long long dx_sq = (long long)(dx - x) * (dx - x);
long long dy_sq = (long long)(dy - y) * (dy - y);
long long r_sq = (long long)r * r;
if (dx_sq + dy_sq <= r_sq) {
ans++;
found = true;
break; // The dart has found the target, check the next dart
}
}
}
if (found) break;
}
if (found) break;
}
}

code:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
import math

n, m = map(int, input().split())

circles = []

min_x = min_y = float('inf')
max_x = max_y = float('-inf')

for _ in range(n):
x, y, r = map(int, input().split())
circles.append((x, y, r))
min_x = min(min_x, x - r)
max_x = max(max_x, x + r)
min_y = min(min_y, y - r)
max_y = max(max_y, y + r)

points = []

for _ in range(m):
dx, dy = map(int, input().split())
points.append((dx, dy))
min_x = min(min_x, dx)
max_x = max(max_x, dx)
min_y = min(min_y, dy)
max_y = max(max_y, dy)

GRID_SIZE = 500
delta_x = max_x - min_x
delta_y = max_y - min_y
s = max(delta_x, delta_y) / GRID_SIZE
if s == 0:
s = 1

# Function that maps coordinates to grid indices
def get_grid_cell(x_n, y_n):
gx = int((x_n - min_x) / s)
gy = int((y_n - min_y) / s)
return gx, gy

grid = {}

# Mapping the targets onto the grid
for idx, (x, y, r) in enumerate(circles):
x_min = x - r
x_max = x + r
y_min = y - r
y_max = y + r
gx_min, gy_min = get_grid_cell(x_min, y_min)
gx_max, gy_max = get_grid_cell(x_max, y_max)
for gx in range(gx_min, gx_max + 1):
for gy in range(gy_min, gy_max + 1):
if (gx, gy) not in grid:
grid[(gx, gy)] = []
grid[(gx, gy)].append(idx) # store the target index

ans = 0

# For each dart, check the target in the grid where it is located
for dx, dy in points:
gx, gy = get_grid_cell(dx, dy)
found = False
if (gx, gy) in grid:
for idx in grid[(gx, gy)]:
x, y, r = circles[idx]
# Determine if the dart is in the target
if (dx - x) ** 2 + (dy - y) ** 2 <= r ** 2:
ans += 1
found = True
break # 找到后跳出循环
# The grids do not overlap and the surrounding grids are not detected?

print(ans)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
#include <iostream>
#include <vector>
#include <cmath>
#include <unordered_map>
#include <algorithm>
#include <climits>

using namespace std;

int main() {
// Fast input/output
ios::sync_with_stdio(false);
cin.tie(NULL);

int n, m;
cin >> n >> m;

vector<tuple<int, int, int>> circles;
long long min_x = LLONG_MAX, min_y = LLONG_MAX;
long long max_x = LLONG_MIN, max_y = LLONG_MIN;

// Read circles and update bounding box
for (int i = 0; i < n; ++i) {
int x, y, r;
cin >> x >> y >> r;
circles.emplace_back(x, y, r);
min_x = min(min_x, (long long)x - r);
max_x = max(max_x, (long long)x + r);
min_y = min(min_y, (long long)y - r);
max_y = max(max_y, (long long)y + r);
}

vector<pair<int, int>> points;

// Read darts and update bounding box
for (int i = 0; i < m; ++i) {
int dx, dy;
cin >> dx >> dy;
points.emplace_back(dx, dy);
min_x = min(min_x, (long long)dx);
max_x = max(max_x, (long long)dx);
min_y = min(min_y, (long long)dy);
max_y = max(max_y, (long long)dy);
}

const int GRID_SIZE = 500;
long long delta_x = max_x - min_x;
long long delta_y = max_y - min_y;
double s = max(delta_x, delta_y) / (double)GRID_SIZE;
if (s == 0) {
s = 1;
}

// Function to get grid cell indices
auto get_grid_cell = [&](long long x_n, long long y_n) {
int gx = int((x_n - min_x) / s);
int gy = int((y_n - min_y) / s);
return make_pair(gx, gy);
};

// Function to combine gx and gy into a single key
auto get_grid_key = [](int gx, int gy) -> long long {
return ((long long)gx << 32) | (unsigned int)gy;
};

// Map from grid cell key to list of circle indices
unordered_map<long long, vector<int>> grid;

// Map circles to grid cells
for (int idx = 0; idx < n; ++idx) {
int x, y, r;
tie(x, y, r) = circles[idx];
long long x_min = x - r;
long long x_max = x + r;
long long y_min = y - r;
long long y_max = y + r;
auto [gx_min, gy_min] = get_grid_cell(x_min, y_min);
auto [gx_max, gy_max] = get_grid_cell(x_max, y_max);
for (int gx = gx_min; gx <= gx_max; ++gx) {
for (int gy = gy_min; gy <= gy_max; ++gy) {
long long key = get_grid_key(gx, gy);
grid[key].push_back(idx); // Store circle index
}
}
}

int ans = 0;

// For each dart, check circles in its grid cell and adjacent cells
for (const auto& p : points) {
int dx = p.first;
int dy = p.second;
auto [gx, gy] = get_grid_cell(dx, dy);
bool found = false;

// Check the dart's grid cell and its 8 neighbors
for (int ix = gx - 1; ix <= gx + 1; ++ix) {
for (int iy = gy - 1; iy <= gy + 1; ++iy) {
long long key = get_grid_key(ix, iy);
if (grid.count(key)) {
const auto& circle_indices = grid[key];
for (int idx : circle_indices) {
int x, y, r;
tie(x, y, r) = circles[idx];
// Check if the dart is inside the circle
long long dx_sq = (long long)(dx - x) * (dx - x);
long long dy_sq = (long long)(dy - y) * (dy - y);
long long r_sq = (long long)r * r;
if (dx_sq + dy_sq <= r_sq) {
ans++;
found = true;
break; // Move to next dart
}
}
}
if (found) break;
}
if (found) break;
}
}

cout << ans << '\n';
return 0;
}
  • Python
  • C++
  • Contest
  • Inter-Uni Programming Contest

show all >>

9021_TUT_1

  2024-09-11
字数统计: 626字   |   阅读时长: 3min

Slide 1: Introduction

Today, we are going to walk through six Python functions that perform various tasks involving integers, lists, and text files. Each function demonstrates different ways to manipulate data, including string formatting, list processing, and reading from files.

Slide 2: Function 1 - f1(m, n)

The first function, f1, generates a simple string pattern. Here’s how it works:

1
2
def f1(m, n):
return ('|' + '_' * n + '|') * m
  1. The function takes two integer arguments, m and n. Both are assumed to be at least 0.
  2. It constructs a pattern consisting of vertical bars (|) enclosing underscores (_), repeated m times. The number of underscores between the bars is determined by n.
  3. For example, if m = 3 and n = 4, the output would be:
1
|____||____||____|

Slide 3: Function 2 - f2(n)

The second function, f2, creates a square pattern made up of digits. Here’s the function:

1
2
def f2(n):
return (str(n) * n + '\n') * n
  1. This function takes an integer n and generates a square of n rows, where each row contains the digit n repeated n times.
  2. The pattern ends with a newline after each row.
  3. For example, if n = 3, the output will be:
1
2
3
333
333
333

Slide 4: Function 3 - f3(L)

Next, we have f3, which works on a list of integers:

1
2
3
4
def f3(L):
while len(L) > 1 and L[0] > L[1]:
L.remove(L[0])
print(L)
  1. This function removes elements from the start of the list until the first two consecutive elements are in non-decreasing order.
  2. The process continues as long as the first element is strictly greater than the second element.
  3. Once the list is stable, it prints the modified list.
  4. For example, if L = [9, 8, 7, 10], the function will remove 9, 8, and 7, leaving [10].

Slide 5: Function 4 - f4(D, n)

The fourth function, f4, works with dictionaries:

1
2
3
4
5
6
7
8
def f4(D, n):
if n not in D:
return []
ans = [n]
while n in D and D[n] > n:
ans.append(D[n])
n = D[n]
return ans
  1. This function takes a dictionary D and an integer n. It generates a strictly increasing sequence of integers based on the relationships defined in the dictionary.
  2. Starting from n, it appends D[n], D[D[n]], and so on to the list, as long as each subsequent value is greater than the previous one.
  3. For example, if D = {1: 2, 2: 3, 3: 5} and n = 1, the function will return [1, 2, 3, 5].

Slide 6: Function 5 - f5(filename)

The fifth function, f5, reads from a file and processes each line:

1
2
3
4
5
6
def f5(filename):
with open(filename) as f:
for i in f:
name, number = i.split(',')
number = int(number) * 1000
print(f"{number} people named {name}")
  1. This function reads a text file, where each line consists of a name and a count separated by a comma.
  2. The function multiplies the count by 1000 and prints the result in the format: “X people named Y”.
  3. For example, if the file contains a line “John,5”, it will print:
1
5000 people named John

Slide 7: Function 6 - f6(filename)

The final function, f6, also reads from a text file, but with a different format:

1
2
3
4
5
6
def f6(filename):
with open(filename) as f:
for i in f:
if not i.isspace():
number, charactor = i.split()
print(int(number) * charactor)
  1. This function reads lines that contain an integer followed by a symbol (e.g., “5 *”).
  2. It multiplies the symbol by the integer and prints the result.
  3. For example, if the file contains the line “3 # “, the function will print:
1
### 
  • Python
  • Tutorial

show all >>

964E

  2024-08-07
字数统计: 527字   |   阅读时长: 3min

Question:

E. Triple Operations
time limit per test
1 second
memory limit per test
256 megabytes
input
standard input
output
standard output

On the board Ivy wrote down all integers from ll to rr, inclusive.

In an operation, she does the following:

  • pick two numbers xx and yy on the board, erase them, and in their place write the numbers 3x3x and ⌊y3⌋⌊y3⌋. (Here ⌊∙⌋⌊∙⌋ denotes rounding down to the nearest integer).

What is the minimum number of operations Ivy needs to make all numbers on the board equal 00? We have a proof that this is always possible.

Input

The first line contains an integer tt (1≤t≤1041≤t≤104) — the number of test cases.

The only line of each test case contains two integers ll and rr (1≤l<r≤2⋅1051≤l<r≤2⋅105).

Output

For each test case, output a single integer — the minimum number of operations needed to make all numbers on the board equal 00.

Example
Input
Copy
4
1 3
2 4
199999 200000
19 84
Output
Copy
5
6
36
263
Note

In the first test case, we can perform 55 operations as follows:

1,2,3−→−−−−x=1,y=23,0,3−→−−−−x=0,y=31,0,3−→−−−−x=0,y=31,0,1−→−−−−x=0,y=10,0,1−→−−−−x=0,y=10,0,0.1,2,3→x=1,y=23,0,3→x=0,y=31,0,3→x=0,y=31,0,1→x=0,y=10,0,1→x=0,y=10,0,0.

[964E.md](https://codeforces.com/contest/1999/problem/E)

My think:

At first, I thought it was a simple simulation problem: calculate the number of times x when the smallest
number divided by 3 equals 0, and then the answer would be x * 2 plus the number of remaining times when
the left number divided by 3 equals 0. However, this approach is incorrect.

By utilizing the characteristics of exponential growth and performing some simple
calculations, we can quickly determine the minimum number of operations within a given range.
This method has a low time complexity and can efficiently handle large input ranges.

Code:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
import math
t = int(input())
for i in range(t):
num = list(map(int, input().split()))
l = num[0]
r = num[1]
start_pow3 = 1
cnt_start = 1
while start_pow3 <= (l / 3):
start_pow3 *= 3
cnt_start += 1
ans = cnt_start
pow3 = start_pow3
next_pow3 = start_pow3 * 3
while pow3 <= r:
ans += (min(r + 1, next_pow3) - max(l, pow3)) * cnt_start
cnt_start += 1
pow3 *= 3
next_pow3 *= 3
print(ans)

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
def min_operations_to_zero(n):
operations = 0
while n > 0:
n = n // 3
operations += 1
return operations

t = int(input())
results = []
for _ in range(t):
l, r = map(int, input().split())
total_operations = 0
oper = min_operations_to_zero(l)
for n in range(l+1, r+1):
total_operations += min_operations_to_zero(n)
total_operations += oper*2
results.append(total_operations)

for result in results:
print(result)
  • Python
  • Answer

show all >>

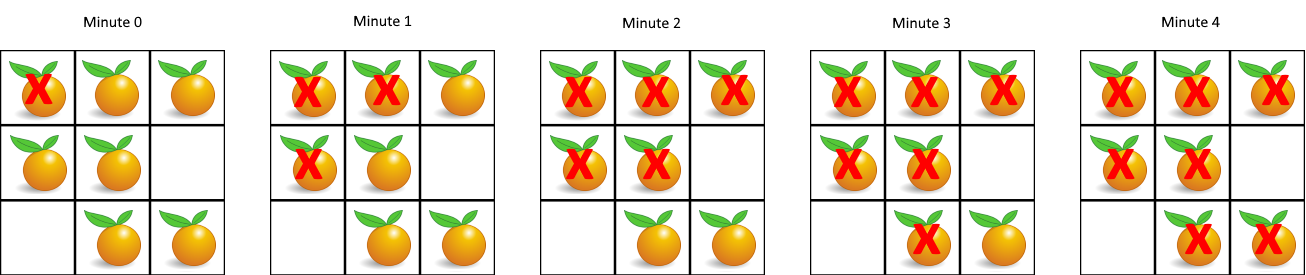
994.Rotten orange

  2024-05-14
字数统计: 739字   |   阅读时长: 4min

topic:

“””

Given m x n grid  grid middle,Each cell can have one of the following three values:

  • value 0 Represents the empty unit;
  • value 1 Represents fresh oranges;
  • value 2 代表Rotten orange。

every minute,Rotten orange around 4 Adjacent in this direction Fresh oranges will rot。

return 直到单元格middle没有新鲜橘子为止所必须经过的最小分钟数。If it is impossible,return -1 。


Exemplary example 1:

enter:grid = [[2,1,1],[1,1,0],[0,1,1]]
Output:4

Exemplary example 2:

enter:grid = [[2,1,1],[0,1,1],[1,0,1]]
Output:-1
explain:Orange in the lower left corner(First 2 OK, First 0 List)Never rot,Because rotten will only happen in 4 In the direction。

Exemplary example 3:

enter:grid = [[0,2]]
Output:0
explain:because 0 There is no fresh orange in minutes,So the answer is 0 。


hint:

  • m == grid.length
  • n == grid[i].length
  • 1 <= m, n <= 10
  • grid[i][j] Only for 0、1 or 2
Related Topics
  • Priority search
  • Array
  • matrix

  • 👍 872
  • 👎 0
  • """

    Thought:

    这个问题可以用Priority search(BFS)To solve。We need to track the spread of rotten oranges,Record time,And check if there is a fresh orange that cannot be rotten。The initial idea of ​​the original idea:

    1
    2
    3
    4
    5
    6
    7
    8
    9
    class Solution:
    def orangesRotting(self, grid: List[List[int]]) -> int:
    bad_orange = []
    # 找到所有初始Rotten orange
    for i in range(len(grid)):
    for j in range(len(grid[0])):
    if grid[i][j] == 2:
    # 存入初始队List
    bad_orange.append((i, j))

    Similar to multi -threaded,每个线程存入一个初始队List,初始队List通过BFSGradual diffusion

    Code:

    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    16
    17
    18
    19
    20
    21
    22
    23
    24
    25
    26
    27
    28
    29
    30
    31
    32
    33
    34
    35
    36
    37
    38
    from collections import deque

    class Solution:
    def orangesRotting(self, grid: List[List[int]]) -> int:
    bad_orange = deque()
    fresh_oranges = 0
    rows, cols = len(grid), len(grid[0])

    # 找到所有初始Rotten orange,And calculate the number of fresh oranges
    for i in range(rows):
    for j in range(cols):
    if grid[i][j] == 2:
    bad_orange.append((i, j))
    elif grid[i][j] == 1:
    fresh_oranges += 1

    # 方向Array:up down left right
    directions = [(0, 1), (1, 0), (0, -1), (-1, 0)]

    # If there is no fresh orange,直接return 0
    if fresh_oranges == 0:
    return 0

    # BFS
    minutes = 0
    while bad_orange:
    minutes += 1
    for _ in range(len(bad_orange)):
    x, y = bad_orange.popleft()
    for dx, dy in directions:
    nx, ny = x + dx, y + dy
    if 0 <= nx < rows and 0 <= ny < cols and grid[nx][ny] == 1:
    grid[nx][ny] = 2
    fresh_oranges -= 1
    bad_orange.append((nx, ny))

    # If there are fresh oranges,return -1
    return minutes - 1 if fresh_oranges == 0 else -1
    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    16
    17
    18
    19
    20
    21
    22
    23
    24
    25
    26
    27
    28
    29
    30
    31
    32
    33
    34
    35
    36
    37
    38
    39
    40
    41
    42
    43
    44
    45
    46
    47
    48
    49
    50
    51
    52
    53
    54
    55
    56
    57
    58
    59
    import (
    "sync"
    )

    func orangesRotting(grid [][]int) int {
    rows, cols := len(grid), len(grid[0])
    badOranges := make([][2]int, 0)
    freshOranges := 0

    // 找到所有初始Rotten orange,And calculate the number of fresh oranges
    for r := 0; r < rows; r++ {
    for c := 0; c < cols; c++ {
    if grid[r][c] == 2 {
    badOranges = append(badOranges, [2]int{r, c})
    } else if grid[r][c] == 1 {
    freshOranges += 1
    }
    }
    }

    // If there is no fresh orange,直接return 0
    if freshOranges == 0 {
    return 0
    }

    directions := [][2]int{{0, 1}, {1, 0}, {0, -1}, {-1, 0}}
    minutes := 0

    var wg sync.WaitGroup

    // BFS
    for len(badOranges) > 0 {
    minutes++
    nextBadOranges := make([][2]int, 0)
    for _, orange := range badOranges {
    x, y := orange[0], orange[1]
    wg.Add(1)
    go func(x, y int) {
    defer wg.Done()
    for _, d := range directions {
    nx, ny := x+d[0], y+d[1]
    if nx >= 0 && nx < rows && ny >= 0 && ny < cols && grid[nx][ny] == 1 {
    grid[nx][ny] = 2
    nextBadOranges = append(nextBadOranges, [2]int{nx, ny})
    freshOranges--
    }
    }
    }(x, y)
    }
    wg.Wait()
    badOranges = nextBadOranges
    }

    // If there are fresh oranges,return -1
    if freshOranges > 0 {
    return -1
    }
    return minutes - 1
    }
    • Python
    • BFS
    • Bilateral queue

    show all >>

    1017. Negative binary conversion

      2024-01-01
    字数统计: 133字   |   阅读时长: 1min

    topic:

    1017. Negative binary conversion

    Thought:

    The difference from binary is just not always//2,It’s every number//-1

    Code:

    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    class Solution:
    def baseNeg2(self, n: int) -> str:
    k = 1
    ans = []
    while n:
    if n % 2:
    ans.append('1')
    n -= k
    else:
    ans.append('0')
    n //= 2
    k *= -1
    return ''.join(ans[::-1]) or '0'
    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    16
    17
    18
    19
    impl Solution {
    pub fn base_neg2(mut n: i32) -> String {
    let mut ans = Vec::new();
    while n != 0 {
    if n % 2 != 0 {
    ans.push('1');
    n = (n - 1) / -2;
    } else {
    ans.push('0');
    n /= -2;
    }
    }
    if ans.is_empty() {
    ans.push('0');
    }
    ans.reverse();
    ans.iter().collect()
    }
    }
    • Python
    • answer

    show all >>

    1017.Negative binary conversion

      2024-01-01
    字数统计: 223字   |   阅读时长: 1min

    topic:

    Give you an integer n ,Return to the integer in the form of a binary string Negative binary(base -2)express。

    Notice,Unless the string is "0",Otherwise, the returned string cannot contain the front guide zero。


    Exemplary example 1:

    enter:n = 2
    Output:"110"
    explain:(-2)2 + (-2)1 = 2
    

    Exemplary example 2:

    enter:n = 3
    Output:"111"
    explain:(-2)2 + (-2)1 + (-2)0 = 3
    

    Exemplary example 3:

    enter:n = 4
    Output:"100"
    explain:(-2)2 = 4


    hint:

    • 0 <= n <= 109
    Related Topics
  • math

  • 👍 111
  • 👎 0
  • [1017.Negative binary conversion.md]()

    Thought:

    We can judge n Every bit from low to high,If the bit is 1,Then the answer is 1,Otherwise 0。If the bit is 1,So we need to n minus k。Next we update n=⌊n/2⌋, k=−k。Continue to judge the next。
    at last,We will return to the answer。
    time complexity O(logn),in n For the given integer。Ignore the space consumption of the answer,Spatial complexity O(1)。

    Code:

    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    class Solution:
    def baseNeg2(self, n: int) -> str:
    k = 1
    ans = []
    while n:
    if n % 2:
    ans.append('1')
    n -= k
    else:
    ans.append('0')
    n //= 2
    k *= -1
    return ''.join(ans[::-1]) or '0'
    • Python
    • answer

    show all >>

    1124. The longest period of performance One question daily

      2024-01-01
    字数统计: 265字   |   阅读时长: 1min

    topic:

    2023-02-15.png
    1124. The longest period of performance.md

    Thought:

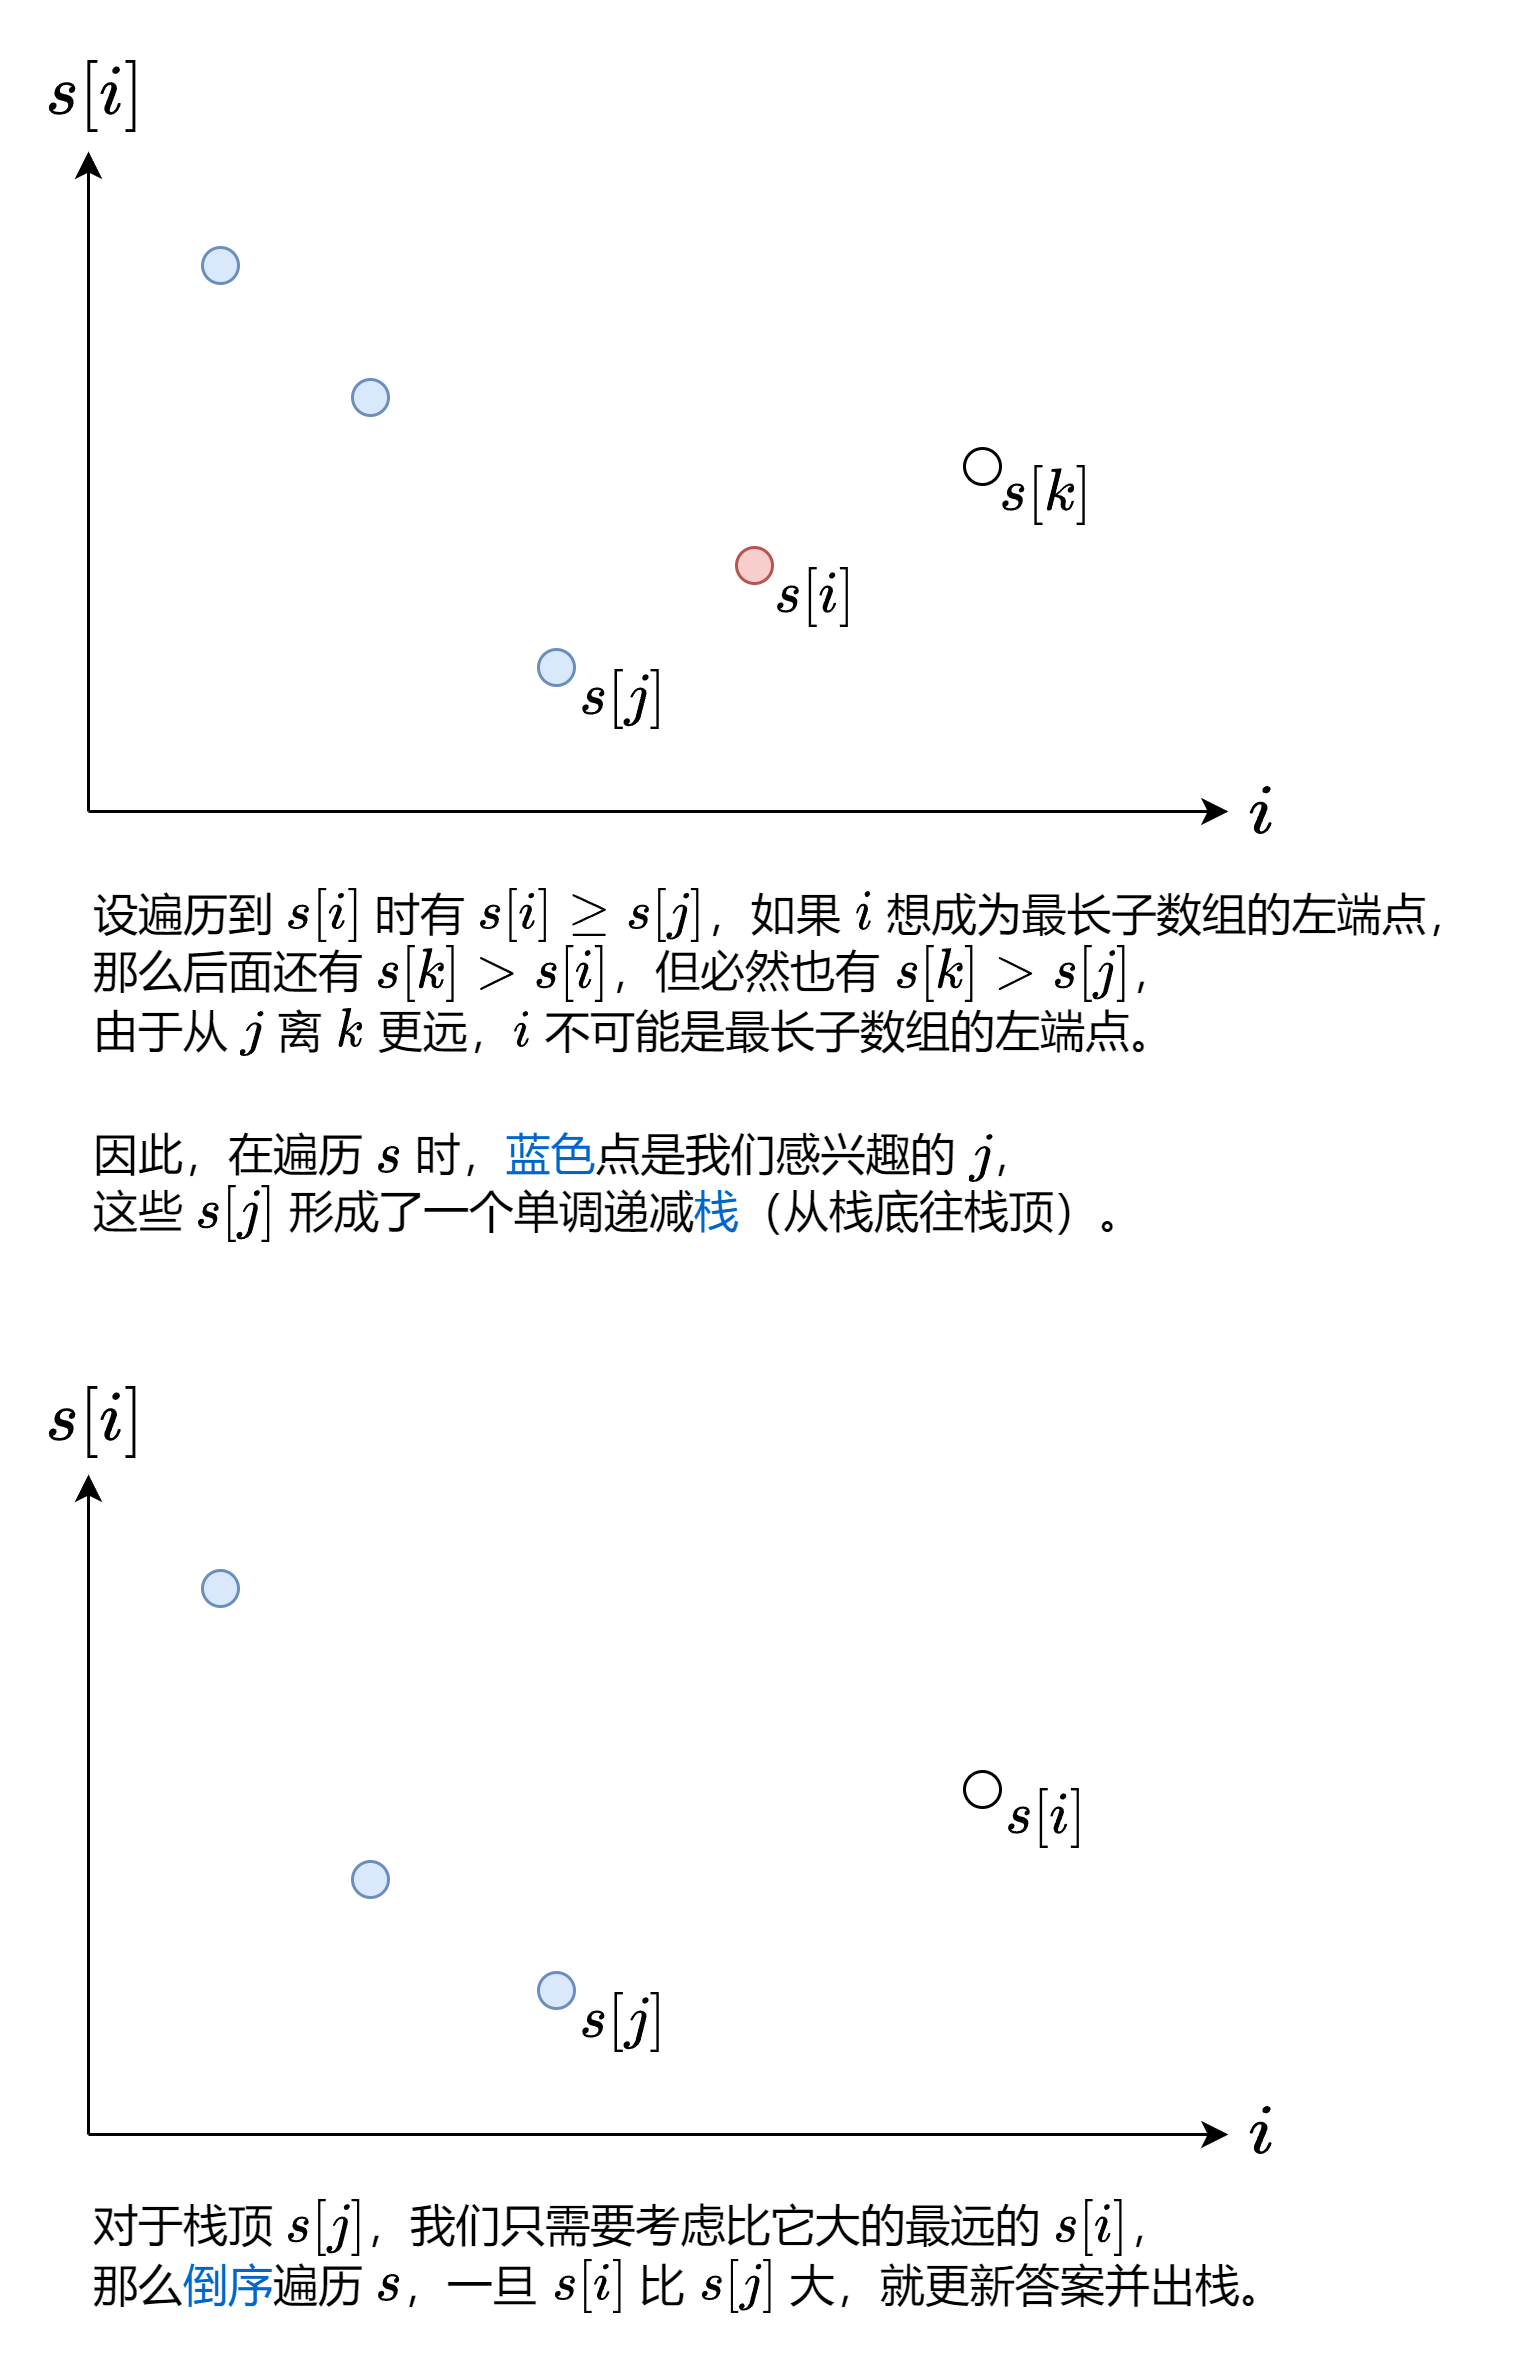
    This question is not,I thought it was a double pointer but timeout over time,结果是Prefix and算法。The following isSpiritual godSolution
    通过Prefix and,我们可以把Elements and elements of sub -array转换成两个Prefix and的差,Right now
    $$
    \sum_{j=left}^{right} nums[j] = \sum_{j=0}^{right} nums[j]− \sum_{j=0}^{left-1} nums[j]=s[right+1]−s[left]
    $$
    Now that I said it「Elements and elements of sub -array」,那么利用Prefix and s,Turn the problem to:
    Find two bidding i and j,satisfy j<ij<ij<i and s[j]<s[i],maximize i−jValue。

    Code:

    Double pointer
    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    class Solution:
    def longestWPI(self, hours: List[int]) -> int:
    ans = 0
    for index, i in enumerate(hours):
    count = 0
    j = index
    while j < len(hours):
    if hours[j] <= 8:
    count -= 1
    elif hours[j] > 8:
    count += 1
    if count > 0:
    ans = max(ans, j - index + 1)
    j += 1
    return ans
    Prefix and
    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    class Solution:
    def longestWPI(self, hours: List[int]) -> int:
    n = len(hours)
    s = [0] * (n + 1)
    st = [0]
    for j, h in enumerate(hours, 1):
    s[j] = s[j - 1] + (1 if h > 8 else -1)
    if s[j] < s[st[-1]]:
    st.append(j)
    ans = 0
    for i in range(n, 0 , -1):
    while st and s[i] > s[st[-1]]:
    ans = max(ans, i-st.pop())
    return ans
    • Python
    • answer
    • Prefix and

    show all >>

    1138. The path on the letter board One question daily

      2024-01-01
    字数统计: 311字   |   阅读时长: 1min

    topic:

    2023-02-12.png
    1138. The path on the letter board One question daily.md

    Thought:

    Read the wrong questions,According to the method of random letters above the subtitle version。butzSpecial circumstances are not considered,I thought about it later,Just turn the column into a line,Time complexity isOn3
    。Look atylbs answer,Use directlyasciiThe code watch simulates a letter board。

    From the starting point (0,0)(0, 0)(0,0) Set off,Simulate each step of movement,Style the movement of each step into the answer。Pay attention to the direction of moving“Left、superior、right、Down”Order。

    Code:

    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    16
    17
    18
    19
    20
    21
    22
    23
    24
    25
    26
    27
    28
    29
    30
    31
    32
    33
    class Solution:
    def alphabetBoardPath(self, target: str) -> str:
    str1 = ""
    board = ["abcde",
    "fghij",
    "klmno",
    "pqrst",
    "uvwxy",
    "z"]
    now_i = 0
    now_j = 0
    for i in board:
    for j,value in enumerate(i):
    pass
    for char in target:
    # See which line is
    for i in range(len(board)):
    if char in board[i]:
    if i - now_i > 0:
    str1 += 'D' * (i - now_i)
    if i - now_i < 0:
    str1 += 'U' * (now_i - i)
    now_i = i
    # Which column
    for j, value in enumerate(board[i]):
    if value == char:
    if j - now_j > 0:
    str1 += 'R' * (j - now_j)
    if j - now_j < 0:
    str1 += 'L' * (now_j - j)
    str1 += '!'
    now_j = j
    return str1
    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    16
    17
    18
    19
    20
    21
    class Solution:
    def alphabetBoardPath(self, target: str) -> str:
    i = j = 0
    ans = []
    for char in target:
    v = ord(char) - ord("a")
    x, y = v // 5, v % 5
    while j > y:
    j -= 1
    ans.append("L")
    while i > x:
    i -= 1
    ans.append("U")
    while j < y:
    j += 1
    ans.append("R")
    while i < x:
    i += 1
    ans.append("D")
    ans.append("!")
    return "".join(ans)
    • Python
    • answer

    show all >>

    << 上一页123456…16下一页 >>

    152 篇 | 132.6k
    次 | 人
    这里自动载入天数这里自动载入时分秒
    2022-2026 loong loong | 新南威尔士龙龙号